In my previous posts, I made a big play about the transparency of XBRL and how for example XBRL to XL leverages this. However in reality our application has never fully exploited these possibilities, until now. Yes you could view the “as presented” data used in the standard formula by switching to the relevant filing sheet to see the company's financial statements and notes as laid out in the paper version of the 10-K. But there was no direct link, no instant drill down.
Not only do I think that transparency is essential in a constructing a robust model and critical in ensuring you don't deal on the wrong number, it's also rather thrilling to be magically transported back from a headline figure to it's underlying components, displayed just as the company disclosed them.
The following screen shots don't really do it justice as you kinda need to see it in action so you may want to watch the video instead. The latest XBRL Sheet example, downloadable from here, contains the new "Standard" sheet that enables the top to bottom drill down shown here using the two included macros. The macro code can also be downloaded from there separately as a VBA module (Basically just a text file with the code in).
We have created two simple functions that enable you to rapidly move around the data to gain an understanding of the underlying values, where they came from and to verify their accuracy.
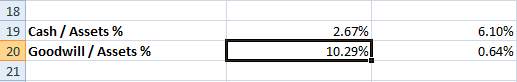
XDrillDown (assigned the short cut key ctrl y in the example sheet) drills down to the next layer of the data. So if you are in the "Model" sheet as in the example above, pressing this short cut will take you the components of the selected ratio. The result of which is shown below.
XDrillAcross (short cut key ctrl l - not 1 but the letter as in "level") drills across the same level to show you any of the other components in this layer of the ratio. So pressing the short cut will take you to the other component of "Goodwill/Total Assets" as shown by my arrow. Continually pressing XDrillAcross will cycle through the components in turn so another press will take you back in this case to Goodwill.
If you use XDrillDown on any of these components, it will take you to the next layer (shown below) and reveal where the "Standard" items found these values in the "as reported" XBRL "Filing" sheets downloaded using XBRL Sheet from xbrlxl.com. Now you can see just where these values came from in the 10-K or 10-Q. And again if you use XDrillAcross, it knows where the next component is, so will take you there (as indicated again by my arrow).
This is made possible by a small change we have made to XBRL Sheet. The Standard sheet (see the example above but one with "C69" circled) now has extra columns in it that represent the links to their as reported values.
How do I get back to the different layers? Well each layer is represented by a tab, so just click on the "layer" you want to look at again and the ratio or data item you previously drilled through will still be highlighted.
Just to complete the picture, if you use XDrillDown on a formula which contains a value on the same sheet (e.g. ROCE below), it will reveal every value on the same sheet using arrows (any values on another sheet will be indicated by a dotted line to a "sheet" symbol and can be cycled using XDrillAcross in the usual way). Press XDrillDown again and the arrows will disappear.
It's worth noting these functions can be used to validate any formula with components so could be used for tick back in any spreadsheet you have created with or without XBRL.
These functions aren't doing anything particularly clever, merely packaged up to use existing functionality built into Excel. I'm not big into wheel re-invention. But hopefully they will enable you to take full advantage of the transparency built into XBRL, as implemented by us in XBRL Sheet.
Showing posts with label xbrl. Show all posts
Thursday, 7 November 2013
Transparent data - drilling down using XBRL
Labels:
10-K,
10-Q,
analysis,
as reported,
audit,
components,
drill down,
excel,
financial analysis,
formula,
function,
macro,
spreadsheet,
tick back,
transparent,
validation,
vba,
xbrl
Wednesday, 17 July 2013
XBRL Sheet - Direct access to XBRL from within Excel
You may have a read these 2 previous posts Instant Comparisons of XBRL in Excel and Looking up XBRL in Excel so you probably know where I am coming from and with the launch of XBRL Sheet we are getting even closer.
You no longer need to leave the comfort of Excel in order to download reams of XBRL data. Through the wonder of web queries, XBRL Sheet provides instant access to the latest filings for an unlimited number of companies. Want to add an additional company to your model, no problem, just create a new query or better still copy an existing one and change the "Co Id" parameter. Want to load up an older filing, just change the period parameter. See the FAQ's for more information on how to do this.
The example spreadsheet downloadable from here follows the same Model/Standard/XBRL arrangement that allows you to hack the data without disturbing your model (or trash the model without effecting your ability to populate a new one - see Looking up XBRL in Excel).
Now, using web queries, you can ensure that the model is always up to date. Set the external data range option to refresh on opening and if you are using the same period parameter that I've set in the example spreadsheet, it will always download the latest filings on opening.
The other beauty of using web queries is that they can quickly be incorporated into a VBA macro so say you wanted to home in on a particular value or ratio for 100 companies, you could write a VBA Macro using XBRL Sheet to do just that. In fact I ought to knock one up and put it in a future post!
Watch the "How To" video here, download the example spreadsheet here and read the FAQ's here.
And to understand more about web queries, you may want to visit this site. Or if you are using a Mac, try this one.
UPDATE: New video to watch showing how to access 10 years of data in the very latest version and here's the post that goes with it.
Now back to the data issues......
You no longer need to leave the comfort of Excel in order to download reams of XBRL data. Through the wonder of web queries, XBRL Sheet provides instant access to the latest filings for an unlimited number of companies. Want to add an additional company to your model, no problem, just create a new query or better still copy an existing one and change the "Co Id" parameter. Want to load up an older filing, just change the period parameter. See the FAQ's for more information on how to do this.
The example spreadsheet downloadable from here follows the same Model/Standard/XBRL arrangement that allows you to hack the data without disturbing your model (or trash the model without effecting your ability to populate a new one - see Looking up XBRL in Excel).
Now, using web queries, you can ensure that the model is always up to date. Set the external data range option to refresh on opening and if you are using the same period parameter that I've set in the example spreadsheet, it will always download the latest filings on opening.
The other beauty of using web queries is that they can quickly be incorporated into a VBA macro so say you wanted to home in on a particular value or ratio for 100 companies, you could write a VBA Macro using XBRL Sheet to do just that. In fact I ought to knock one up and put it in a future post!
Watch the "How To" video here, download the example spreadsheet here and read the FAQ's here.
And to understand more about web queries, you may want to visit this site. Or if you are using a Mac, try this one.
UPDATE: New video to watch showing how to access 10 years of data in the very latest version and here's the post that goes with it.
Now back to the data issues......
Labels:
analysis,
analyst,
app,
automatic updates,
comparative analysis,
credit analysis,
direct,
easy,
excel,
financial analysis,
model,
sec,
sheet,
spreadsheet,
vba,
web query,
xbrl,
xbrl tags,
xbrl to xl
Thursday, 2 May 2013
The case against extensions
Thinking again about Daniel Robert's recent post and the virtue of extensions... And shocked to find myself, at the recent International XBRL conference, one of the few to put my hand up in favour of extensions, I thought it might be worth exploring the other extreme - the absence of extensions.
The exclusive use of GAAP tags would give data vendors and wholesale users of data (e.g quants) what they crave - data they can normalize. Of course there are arguments that there is some data that can never be normalized but that won't stop people trying when the goal is to model the world (well maybe an economy or a sector).
So what would be the cost? Would a company's performance suddenly be mis-represented? Would the subtleties of it's economic contribution now become masked?
Isn't that the point of the label (data item description)?
For those who want a more nuanced understanding of a company's business achievements, they merely need to disregard the tags and focus their attention on the labels column. As per Daniel's piece, this applies equally to companies who wish to engage in the art of obfuscation. Isn't this the beauty of XBRL, you have enough data for everyone provided each type is used correctly?
OK so a tag may not fully describe the nature of a data value but the vendors are going to tag it with something anyway. Better that apples are tagged as fruit than risk them being tagged as oranges.
Ultimately this must be advantageous to companies, as rather than the aggregated holes into which their data will fall being decided by a data factory worker on the other side of the world, they get to decide which GAAP tag their precious data will be allocated to.
As James Claus of Moon Capital pointed out at last years US XBRL conference, investors would prefer data which has (if not down right reject data that hasn't) been classified by the companies themselves. And is the reason why Moon capital never use vendor sourced data. Companies need to get precious about their data and XBRL actually allows them to do that.
The exclusive use of GAAP tags would give data vendors and wholesale users of data (e.g quants) what they crave - data they can normalize. Of course there are arguments that there is some data that can never be normalized but that won't stop people trying when the goal is to model the world (well maybe an economy or a sector).
So what would be the cost? Would a company's performance suddenly be mis-represented? Would the subtleties of it's economic contribution now become masked?
Isn't that the point of the label (data item description)?
For those who want a more nuanced understanding of a company's business achievements, they merely need to disregard the tags and focus their attention on the labels column. As per Daniel's piece, this applies equally to companies who wish to engage in the art of obfuscation. Isn't this the beauty of XBRL, you have enough data for everyone provided each type is used correctly?
OK so a tag may not fully describe the nature of a data value but the vendors are going to tag it with something anyway. Better that apples are tagged as fruit than risk them being tagged as oranges.
Ultimately this must be advantageous to companies, as rather than the aggregated holes into which their data will fall being decided by a data factory worker on the other side of the world, they get to decide which GAAP tag their precious data will be allocated to.
As James Claus of Moon Capital pointed out at last years US XBRL conference, investors would prefer data which has (if not down right reject data that hasn't) been classified by the companies themselves. And is the reason why Moon capital never use vendor sourced data. Companies need to get precious about their data and XBRL actually allows them to do that.
Monday, 15 April 2013
Umm Extensions....picking 3 companies at random
I had a conversation recently with a well regarded member of the XBRL community who intimated to me that serious tagging errors were a thing of the past. Now what you see below may not be errors, but they are a serious problem when attempting to automate analysis using XBRL tagging.
You can find the spreadsheet containing the data I've highlighted on the xbrlxl.com website here.
The examples shown are literally the first 3 companies I loaded up in the XBRL to XL software (off the top of my head - I had no fore-knowledge that they contained significant problems). I expected I might have to look at a dozen or so to find anything remarkable but these 3 large corporations quickly scotched that idea. I should stress these are the very latest 10-K's, not the XBRL they put together when they were first trying to get the hang of this stuff,
I've basically highlighted problems that would effect the kind of analysis I might do if I was interested in understanding the performance of these behemoths of US Industry.
So with Boeing (BA), we can't calculate an accurate figure of trade receivables because any money leant to customers to finance purchases is shown as an extension (no us-gaap tag in the 1st column) so we can't add it to trade receivables automatically, as we might, to get a true figure because they haven't used a standard item to classify it. The extension obscures it's true nature when we want to standardize this data.
If we wanted to calculate our own estimate of EPS on a diluted basis, again we would be out of luck as any numerator we re-calculated could not be divided by the correct denominator as this again has been classified using an extension. Also note that the earnings figure used by the company to calculate basic EPS has been obscured by an extension.

Moving on to inventories, we can't calculate a true work in progress figure, again because of the use of an extension. A significant number in the case of Boeing.
General Motors (GM) is even more problematic. I have no S,G & A or equity income because of extensions. I can't get a figure even for depreciation as the amount has been obscured as a segment axis (don't ask! - but it basically makes it very difficult to get hold of a depreciation number this way because it's hidden behind a segment extension).
So this just leaves us with 3M (MMM). And they've managed to hide trade payables behind an extension.
There are more errors (sorry data issues) - I've just picked out the obvious ones in a cursory flick through these 3 companies.
And it might be there are no suitable us-gaap extensions to cover the item they are trying to disclose.
The use of extensions in the ways highlighted above could be seen by some as healthy and in this respect you might want to read a post by Daniel Roberts.
The data you see in the spreadsheet has all been picked out of sheets generated using XBRL to XL (xbrlxl.com). As well as providing XBRL data for analysis, this version highlights any potential errors.
You can find the spreadsheet containing the data I've highlighted on the xbrlxl.com website here.
The examples shown are literally the first 3 companies I loaded up in the XBRL to XL software (off the top of my head - I had no fore-knowledge that they contained significant problems). I expected I might have to look at a dozen or so to find anything remarkable but these 3 large corporations quickly scotched that idea. I should stress these are the very latest 10-K's, not the XBRL they put together when they were first trying to get the hang of this stuff,
I've basically highlighted problems that would effect the kind of analysis I might do if I was interested in understanding the performance of these behemoths of US Industry.
So with Boeing (BA), we can't calculate an accurate figure of trade receivables because any money leant to customers to finance purchases is shown as an extension (no us-gaap tag in the 1st column) so we can't add it to trade receivables automatically, as we might, to get a true figure because they haven't used a standard item to classify it. The extension obscures it's true nature when we want to standardize this data.
If we wanted to calculate our own estimate of EPS on a diluted basis, again we would be out of luck as any numerator we re-calculated could not be divided by the correct denominator as this again has been classified using an extension. Also note that the earnings figure used by the company to calculate basic EPS has been obscured by an extension.
Moving on to inventories, we can't calculate a true work in progress figure, again because of the use of an extension. A significant number in the case of Boeing.
General Motors (GM) is even more problematic. I have no S,G & A or equity income because of extensions. I can't get a figure even for depreciation as the amount has been obscured as a segment axis (don't ask! - but it basically makes it very difficult to get hold of a depreciation number this way because it's hidden behind a segment extension).
So this just leaves us with 3M (MMM). And they've managed to hide trade payables behind an extension.
There are more errors (sorry data issues) - I've just picked out the obvious ones in a cursory flick through these 3 companies.
And it might be there are no suitable us-gaap extensions to cover the item they are trying to disclose.
The use of extensions in the ways highlighted above could be seen by some as healthy and in this respect you might want to read a post by Daniel Roberts.
The data you see in the spreadsheet has all been picked out of sheets generated using XBRL to XL (xbrlxl.com). As well as providing XBRL data for analysis, this version highlights any potential errors.
Monday, 24 September 2012
And Finally: Quarterlies. Accessing Quarterly XBRL in Excel
A bit later than planned but finally you can now select XBRL 10Q filing data in XBRL to XL and analyse it in Excel.
I have created a new template for quarterly data, which automatically gets selected for download if the 1st filing you choose is a 10Q. This has been designed to make the most of both the values for the most recent quarter and the Year To Date (YTD) numbers.
In a quarterly report, a company will in effect report 5 periods worth of data: latest & previous quarter; latest YTD & previous YTD and comparable balance sheet numbers for the start of the year to which the quarter belongs. In the 1st quarter 10Q, the YTD's won't appear.
So in an XBRL quarterly filing, there are in theory up to 5 principal periods but XBRL has two types of concept (or context to use the XBRL parlance) for any given period: one for duration elements (e.g. income statement items) and one for instant elements (e.g. balance sheet items) so that might lead you to think that a quarterly filing has 10 of these things, except that it doesn't because a quarter and a corresponding YTD share the same instant balance sheet date.
This makes lining up periods for comparison tricky. especially the latest YTD which shares the same balance sheet numbers as the quarter. In XBRL to XL, we have duplicated these numbers to create fully comparable columns of data, regardless of whether you are looking at quarter or YTD figures.
In the "Filing" sheets (above), containing the data laid out as it appears in the filed document, 5 columns of data are downloaded: latest & previous quarter; start of year balance sheet; latest & previous YTD. Be aware that generally, no comparable balance sheet figures are included for the previous quarter - you will need to include the filing for the previous quarter for that.
And in the "Standard" sheet, we have created a new control allowing you to toggle between the quarter and YTD values.
Set it to true to see the YTD numbers.
"Control" is a rather over blown description for it - it's just a cell in which you type either true or false! And the item value formulas use this to determine which columns to use in the calculation.
I have created a new template for quarterly data, which automatically gets selected for download if the 1st filing you choose is a 10Q. This has been designed to make the most of both the values for the most recent quarter and the Year To Date (YTD) numbers.
In a quarterly report, a company will in effect report 5 periods worth of data: latest & previous quarter; latest YTD & previous YTD and comparable balance sheet numbers for the start of the year to which the quarter belongs. In the 1st quarter 10Q, the YTD's won't appear.
So in an XBRL quarterly filing, there are in theory up to 5 principal periods but XBRL has two types of concept (or context to use the XBRL parlance) for any given period: one for duration elements (e.g. income statement items) and one for instant elements (e.g. balance sheet items) so that might lead you to think that a quarterly filing has 10 of these things, except that it doesn't because a quarter and a corresponding YTD share the same instant balance sheet date.
This makes lining up periods for comparison tricky. especially the latest YTD which shares the same balance sheet numbers as the quarter. In XBRL to XL, we have duplicated these numbers to create fully comparable columns of data, regardless of whether you are looking at quarter or YTD figures.
In the "Filing" sheets (above), containing the data laid out as it appears in the filed document, 5 columns of data are downloaded: latest & previous quarter; start of year balance sheet; latest & previous YTD. Be aware that generally, no comparable balance sheet figures are included for the previous quarter - you will need to include the filing for the previous quarter for that.
And in the "Standard" sheet, we have created a new control allowing you to toggle between the quarter and YTD values.
Set it to true to see the YTD numbers.
"Control" is a rather over blown description for it - it's just a cell in which you type either true or false! And the item value formulas use this to determine which columns to use in the calculation.
Friday, 7 September 2012
Comparing XBRL: What happened to Step 1?
If you read my last post, you might be wondering what happened to Step 1! Well Step 1 in comparing XBRL is about actually accessing the stuff in the first place in a way that enables you to do comparisons, which is what I've been droning on about in most of my previous posts and what XBRL to XL is all about.
So it would be a bit rubbish if you couldn't actually access all the data, like in XBRL to XL where you can't currently download quarterlies. So rubbish in fact it's time to change this. As from Monday quarterly data will be available and I will talk here about the issues of accessing quarterly data in XBRL and how we have combated them to maximise comparability and transparency.
Labels:
access,
excel,
quarterlies,
quarterly data,
xbrl
Wednesday, 15 February 2012
Instant comparisons of XBRL data in Excel
You want to compare 5 companies using your own unique, highly sophisticated model in Excel. No problem - just visit xbrlxl.com, click the "XBRL to XL" button, select the companies, choose your filings & click the "XBRL to XL" button again. You will then have a spreadsheet on your desktop crammed full of XBRL data ready for Analysis.
(Update: You can now access this data directly from Excel using XBRL Sheet)
Why is it Analyst ready?
1. It comes with the tags so cross-company comparisons are possible.
2. The data is wholly transparent - miraculously the data arrives in Excel just as it appears in the tables of a 10-K or 10-Q document yet through the power of Excel, any XBRL data item can be called up for use in creating standard formulas. Of course this link can be traced back to show in effect where in the original report your normalised data came from. More than that it shows you if any of the data items used by the company are not standard (potentially compromising any comparisons - something that is not visible in the original financial reports).
3. It's "readily" customisable - You choose the years & data items you wish to use. What you can then do with the data is limited only by the near unlimited power of Excel and it's sister applications in Office.
Right that's the sales pitch out of the way! In my previous post I looked at how you could hook up XBRL to a financial model in Excel. I used an Arelle Fact Table from the Arelle GUI as the source but wondered whether this could be made much, much simpler. XBRL to XL is the result of my musings.
XBRL to XL is very easy to use. There are only 2 types of button you need to worry about. The 5 filing buttons and the magic "XBRL to XL" button so 6 in all. So when you have filled in the search fields for your 1st filing, you press the "Filing 1" button. When you want to search for your 2nd filing you press the "Filing 2" button and so on. This is the only thing you really need to remember as if you press the top button ("Filing 1") when you were actually trying to select the 3rd filing, it will replace the details of the 1st filing rather than put them in the 3rd slot.
The more specific you can be with your search criteria, the faster the search, as the filing details of the five filings will be automatically populated in the filing selection box ready for processing. If you know exactly which filings to include, the whole process will take no more than seven clicks (one to select each filing, one for XBRL to XL to do it's thing and one to confirm your download.
The same 5 "Filing" buttons are used if your initial search has not been specific enough and you need to select a company and/or a particular filing. Click on the check box of the particular company/filing you wish to select and then press one of the 5 filing buttons again, depending in which sheet you wish it to appear. You can keep replacing filings in the filing selection box using the filing buttons until you are happy with your choices.
Note these filings can be from 5 different companies or 5 historical filings from the same company or a mixture. There are no restrictions.
Now press the "XBRL to XL" button to get your filings to Excel. XBRL to XL goes and gets the required filings from the SEC and processes the data into Excel. The processing stage for each filing is highly optimised and takes approximately 2 seconds per filing plus the time it takes to retrieve the XBRL instance documents from the SEC.
Once processing has been completed, you can choose to download the spreadsheet or a zipped version. The downloaded spreadsheet can have up to 5 filings of XBRL data stored in separate sheets which will automatically populate the model on the "front" sheet. The current model that is downloaded is very sparse and is there by way of example (for you to improve on!) The mechanics of how this model is connected to the XBRL data is explained in the previous post Looking up XBRL in Excel.
So there you have it - Analyst Ready data in Excel and represents my entry in the XBRL Challenge set by XBRL US. More details can be found on the fact page for my competition entry. You can also watch "XBRL to XL" TV where you will find step by step guides to downloading and using the data.
(Update: You can now access this data directly from Excel using XBRL Sheet)
Why is it Analyst ready?
1. It comes with the tags so cross-company comparisons are possible.
2. The data is wholly transparent - miraculously the data arrives in Excel just as it appears in the tables of a 10-K or 10-Q document yet through the power of Excel, any XBRL data item can be called up for use in creating standard formulas. Of course this link can be traced back to show in effect where in the original report your normalised data came from. More than that it shows you if any of the data items used by the company are not standard (potentially compromising any comparisons - something that is not visible in the original financial reports).
3. It's "readily" customisable - You choose the years & data items you wish to use. What you can then do with the data is limited only by the near unlimited power of Excel and it's sister applications in Office.
Right that's the sales pitch out of the way! In my previous post I looked at how you could hook up XBRL to a financial model in Excel. I used an Arelle Fact Table from the Arelle GUI as the source but wondered whether this could be made much, much simpler. XBRL to XL is the result of my musings.
XBRL to XL is very easy to use. There are only 2 types of button you need to worry about. The 5 filing buttons and the magic "XBRL to XL" button so 6 in all. So when you have filled in the search fields for your 1st filing, you press the "Filing 1" button. When you want to search for your 2nd filing you press the "Filing 2" button and so on. This is the only thing you really need to remember as if you press the top button ("Filing 1") when you were actually trying to select the 3rd filing, it will replace the details of the 1st filing rather than put them in the 3rd slot.
The more specific you can be with your search criteria, the faster the search, as the filing details of the five filings will be automatically populated in the filing selection box ready for processing. If you know exactly which filings to include, the whole process will take no more than seven clicks (one to select each filing, one for XBRL to XL to do it's thing and one to confirm your download.
The same 5 "Filing" buttons are used if your initial search has not been specific enough and you need to select a company and/or a particular filing. Click on the check box of the particular company/filing you wish to select and then press one of the 5 filing buttons again, depending in which sheet you wish it to appear. You can keep replacing filings in the filing selection box using the filing buttons until you are happy with your choices.
Note these filings can be from 5 different companies or 5 historical filings from the same company or a mixture. There are no restrictions.
Now press the "XBRL to XL" button to get your filings to Excel. XBRL to XL goes and gets the required filings from the SEC and processes the data into Excel. The processing stage for each filing is highly optimised and takes approximately 2 seconds per filing plus the time it takes to retrieve the XBRL instance documents from the SEC.
Once processing has been completed, you can choose to download the spreadsheet or a zipped version. The downloaded spreadsheet can have up to 5 filings of XBRL data stored in separate sheets which will automatically populate the model on the "front" sheet. The current model that is downloaded is very sparse and is there by way of example (for you to improve on!) The mechanics of how this model is connected to the XBRL data is explained in the previous post Looking up XBRL in Excel.
So there you have it - Analyst Ready data in Excel and represents my entry in the XBRL Challenge set by XBRL US. More details can be found on the fact page for my competition entry. You can also watch "XBRL to XL" TV where you will find step by step guides to downloading and using the data.
Thursday, 12 January 2012
Looking up XBRL in Excel
This post follows on from previous one - Xbrl Comparative Analysis in Excel. And I have now created two easier ways of getting XBRL into Excel using XBRL to XL and XBRL Sheet.
When building a standard model to represent XBRL data what do we need to be thinking about?
Well my thinking is that we need to use formulas which are:
1. Easy to build
2. Replicable
3. Transparent
And the model needs to be:
4. Re-usable for different entities.
This really has very little to do with XBRL but an awful lot to do with building robust, validatory & maintainable models.
1. Easy to build. We don't want to be spending more time than it's worth building a beautiful model. So we need a standard formula (see above). At a minimum, this formula must reference three components: the relevant data item (e.g. us-gaap:SalesRevenueNet); the entity (e.g. Microsoft); the time period or instant (e.g. 30th June 2011).
Given that each XBRL tag has to be unique and that there are nearly 16,000! of them, their names tend to be long and extremely forgettable so the quickest way to reference a data item is going to be from a handy list. Again Excel is very good at lists so I'd recommend building a list of the items you are most likely to use in a separate sheet (see above), each tagged with a memorable short name (a tag tagging a tag - whatever next!). You can download the US-GAAP taxonomies from XBRL US which you can then load up in Arelle to use as a starting point. Visit Charles Hoffman's blog for more accessible versions and to learn how to navigate around these monsters.
You can then lookup the item you wish to use from your list when building a formula (either by manually selecting the cell or using yet another lookup function). Of course, if you are that way inclined, you can always build a VBA function to do this but I try to avoid these when I can, as they can create clarity, mobility & version issues that then means your model stops working when you least want it to!
As I mentioned in my previous post, it's a good idea to put each company in a separate sheet (see above) so each column references a particular sheet. You need to set this reference up in each column. I made this easy to do by naming each sheet with it's ticker so we just need to add this to each column and then use this cell in each formula. We can even make this automatic which I will come onto when (and if!) I get to point 4. I have created a fixed range "A1:E1000" for each sheet in the standard lookup formula. Potentially this might get exceeded so you need to keep an eye on this when you load new companies. We could get cleverer with this and make it self managing but I'm realising that this post is already ridiculously long! so I'm not.
We can take advantage of our knowledge of how we loaded the data from Arelle into separate sheets to gain some control over which period will appear in each column. We know the latest year of data will be column 5 (see above). So when we use a lookup function, we can specify a year relative to this (also see above). In forecasting models, the last reported year is often regarded as the current year or year "0". Although strictly speaking it isn't. That honour really belongs to the 1st year to be forecast, which is the current financial year but which is actually referred to as year "1". Still with me!? I have adopted this nomenclature in the way we specify the relative year so year "-1" is the year previous to the latest reported year. Things get way more complicated when we try to create composite years but that's a post much further down the line.
The long and short of this is that it's very easy to specify which year you want to see in each column of your model - enter a number relative to the latest year in the relative year row.
So you take the standard lookup formula, choose a data item from a list and put it in the 1st (or data item) column then set the ticker and relative year you want for each column. Simple.
2. Replicable. Now if you've put your dollars ($) in the right place (which I think I have!), you only need to create the formula once and you can copy it all over the spreadsheet and it will work. Phew! point 2 was a hell of a lot shorter than point 1.
3. Transparent. In my standard items and in my ratios, I want to know where my data is coming from so when I get a surprising value, that surprise doesn't last long! With this in mind, I would recommend that each standard item consists of one XBRL item and that this sheet is then in effect just an intermediary layer or step to your analytics. This may seem over-elaborate but trust me - this will save you an awful lot of time in the future. If you want "robust, validatory & maintainable", there is a price. We can do an awful lot more on this and I will in the future because this is important and really is my "value-add".
4. Re-usable. At some point I'm probably going to get bored of analysing Microsoft and Apple and it might even start to dawn on me that Apple will not remain a perpetual money making machine for ever so I'm gonna need some new companies, perhaps even a new model. So I bin my spreadsheet.......No wait - you don't need to - the "back end" will remain valid. You may need to add some new items to the standard layer for your new "front end" analytical model to work but as you've seen above, that's easy. It will be even easier if you do what I've done with my third example.
Each seperate sheet (see above) is now called filing (1), filing (2) etc. So now you can wipe the existing XBRL and load the new data into each respective sheet without having to re-name it. I've used the word "filing" rather than "company" or "entity" as you may wish to re-use this same sheet to do some historical analysis going back across multiple periods and hence multiple filings. This poses no problems whatsoever and you can even flick the relative year between "0" & "-1" depending on whether you wish to use restated data or not.
You maybe wondering why I've put the numbers in brackets rather than say "_1". Well as you may have noticed by now, I'm quite lazy and this fools Excel into thinking that these are duplicate sheet names, which means each time you copy the last sheet, it automatically re-names it incrementing the number inside the brackets by 1 so I don't have to! I don't know why anyone would want to use any other analytical tool - it's a slackers paradise!
Now if only we could simplify the process of getting the raw XBRL data into the spreadsheet in the first place......Ummm, guess what, I might have an idea on that. Stay tuned!
The examples used in this post are available for download from my website (follow the "Spreadsheet Examples" link. Enjoy building your models!
When building a standard model to represent XBRL data what do we need to be thinking about?
Well my thinking is that we need to use formulas which are:
1. Easy to build
2. Replicable
3. Transparent
And the model needs to be:
4. Re-usable for different entities.
This really has very little to do with XBRL but an awful lot to do with building robust, validatory & maintainable models.
1. Easy to build. We don't want to be spending more time than it's worth building a beautiful model. So we need a standard formula (see above). At a minimum, this formula must reference three components: the relevant data item (e.g. us-gaap:SalesRevenueNet); the entity (e.g. Microsoft); the time period or instant (e.g. 30th June 2011).
Given that each XBRL tag has to be unique and that there are nearly 16,000! of them, their names tend to be long and extremely forgettable so the quickest way to reference a data item is going to be from a handy list. Again Excel is very good at lists so I'd recommend building a list of the items you are most likely to use in a separate sheet (see above), each tagged with a memorable short name (a tag tagging a tag - whatever next!). You can download the US-GAAP taxonomies from XBRL US which you can then load up in Arelle to use as a starting point. Visit Charles Hoffman's blog for more accessible versions and to learn how to navigate around these monsters.
You can then lookup the item you wish to use from your list when building a formula (either by manually selecting the cell or using yet another lookup function). Of course, if you are that way inclined, you can always build a VBA function to do this but I try to avoid these when I can, as they can create clarity, mobility & version issues that then means your model stops working when you least want it to!
As I mentioned in my previous post, it's a good idea to put each company in a separate sheet (see above) so each column references a particular sheet. You need to set this reference up in each column. I made this easy to do by naming each sheet with it's ticker so we just need to add this to each column and then use this cell in each formula. We can even make this automatic which I will come onto when (and if!) I get to point 4. I have created a fixed range "A1:E1000" for each sheet in the standard lookup formula. Potentially this might get exceeded so you need to keep an eye on this when you load new companies. We could get cleverer with this and make it self managing but I'm realising that this post is already ridiculously long! so I'm not.
We can take advantage of our knowledge of how we loaded the data from Arelle into separate sheets to gain some control over which period will appear in each column. We know the latest year of data will be column 5 (see above). So when we use a lookup function, we can specify a year relative to this (also see above). In forecasting models, the last reported year is often regarded as the current year or year "0". Although strictly speaking it isn't. That honour really belongs to the 1st year to be forecast, which is the current financial year but which is actually referred to as year "1". Still with me!? I have adopted this nomenclature in the way we specify the relative year so year "-1" is the year previous to the latest reported year. Things get way more complicated when we try to create composite years but that's a post much further down the line.
The long and short of this is that it's very easy to specify which year you want to see in each column of your model - enter a number relative to the latest year in the relative year row.
So you take the standard lookup formula, choose a data item from a list and put it in the 1st (or data item) column then set the ticker and relative year you want for each column. Simple.
2. Replicable. Now if you've put your dollars ($) in the right place (which I think I have!), you only need to create the formula once and you can copy it all over the spreadsheet and it will work. Phew! point 2 was a hell of a lot shorter than point 1.
3. Transparent. In my standard items and in my ratios, I want to know where my data is coming from so when I get a surprising value, that surprise doesn't last long! With this in mind, I would recommend that each standard item consists of one XBRL item and that this sheet is then in effect just an intermediary layer or step to your analytics. This may seem over-elaborate but trust me - this will save you an awful lot of time in the future. If you want "robust, validatory & maintainable", there is a price. We can do an awful lot more on this and I will in the future because this is important and really is my "value-add".
4. Re-usable. At some point I'm probably going to get bored of analysing Microsoft and Apple and it might even start to dawn on me that Apple will not remain a perpetual money making machine for ever so I'm gonna need some new companies, perhaps even a new model. So I bin my spreadsheet.......No wait - you don't need to - the "back end" will remain valid. You may need to add some new items to the standard layer for your new "front end" analytical model to work but as you've seen above, that's easy. It will be even easier if you do what I've done with my third example.
Each seperate sheet (see above) is now called filing (1), filing (2) etc. So now you can wipe the existing XBRL and load the new data into each respective sheet without having to re-name it. I've used the word "filing" rather than "company" or "entity" as you may wish to re-use this same sheet to do some historical analysis going back across multiple periods and hence multiple filings. This poses no problems whatsoever and you can even flick the relative year between "0" & "-1" depending on whether you wish to use restated data or not.
You maybe wondering why I've put the numbers in brackets rather than say "_1". Well as you may have noticed by now, I'm quite lazy and this fools Excel into thinking that these are duplicate sheet names, which means each time you copy the last sheet, it automatically re-names it incrementing the number inside the brackets by 1 so I don't have to! I don't know why anyone would want to use any other analytical tool - it's a slackers paradise!
Now if only we could simplify the process of getting the raw XBRL data into the spreadsheet in the first place......Ummm, guess what, I might have an idea on that. Stay tuned!
The examples used in this post are available for download from my website (follow the "Spreadsheet Examples" link. Enjoy building your models!
Labels:
analytics,
comparative analysis,
easy to build,
excel,
historical analysis,
lookup,
maintainable,
re-usable,
robust,
sec,
simple,
spreadsheet,
transparent,
us-gaap,
validatory,
xbrl
Friday, 6 January 2012
XBRL Comparative Analysis in Excel using the Arelle Fact Table as a source
It's a bit messy and requires you to tidy the data but because the Arelle GUI exposes the XBRL tags with their respective values (see "Xbrl Tags into Excel using Arelle" post), we can harness the power of Excel to finally do what XBRL was supposed to allow us to do in the first place - compare companies.
Five simple steps required for each company you wish to compare.
Step 1 - Load instance document. Arelle allows you to load this directly from the web if you don't feel the need to download and store it locally.
Choose "Open Web..." from the File menu and copy the URL of the instance document into the input box (shown above). There are two ways to find this - the slow way & the quick way. The slow way requires you to click on the "SEC Search" button which takes you to the EDGAR search page, find the company you are looking for, search for the filing etc etc etc.......You may find it quicker to use the "single click" search option available from my website (see post "Easy access to SEC XBRL spreadsheets via a web app").
From my website, enter the company identifier or name, make your single click to search, then right click on the "X" (shown above) for the filing you require and choose to copy the link. Return to Arelle & paste into the input box. Crikey all this just to open an instance document! and that was the easy bit!
Step 2 - Copy the "Fact Table" to Excel. First remove all (well some) of the unwanted (empty) columns. Choose the remove random empty columns option otherwise known as right clicking on the table and choosing "options > ignore dimensions". For more on this, see previous post "Xbrl Tags into Excel using Arelle".
Step 3 - This step isn't entirely necessary but it kinda feels right (and should speed up lookups - see below). Delete all the note sections containing html formatted and therefore difficult to read text by deleting the rows containing this data.
Step 4 - Delete the unwanted columns that the "random" button failed to delete (i.e. most of them). You may need to expand the width of the columns to see which one is which. Don't use the "autofit column width" option to do this quickly as you will end up with some flipping big columns which are then difficult to re-size back to something sensible! Highlight all the columns and set the width manually to something manageable instead. I deleted 19 columns for the Microsoft 10K in the example spreadsheet (see below) to leave me with the 3 key years of data.
Now you in effect have a lookup table with 2 years of balance sheet (or "instance" data in XBRL parlance) and 3 years of "duration" data such as the income statement.
Step 5 - Except lookups won't work because an exact match is needed for unsorted data (would need to be in alpha-numeric order for it to be sorted) and the tags pasted from Arelle have leading spaces consistent with the presentation hierarchy, so another step is needed. Insert a new column in front of the tags and fill it with the following formula "=trim(B1)" using a relative cell reference to replicate the "tags" column but with the leading spaces removed (as shown above).
Now do it all over again for the next company you wish to compare! putting it in a new sheet.
Because the tags are the same* regardless of which company you are looking at, you can now use Excel's lookup functions to create standard reports for comparative analysis. Order is unimportant for exact lookup functions, which is what enables us to do this regardless of how the company has chosen to present the data.
The beauty of this is that you can load the data "as presented" whilst viewing the data in a standardised format customised to your choice. Standardised and as presented data connected and all in the same file. Now that is powerful and only possible because of XBRL. More on the mechanics of how to create a standard report for multiple companies in my next post. For now have a look at the example spreadsheet (snippets above) which you can download from my website - www.xbrlxl.com (follow the "Spreadsheet Examples" link on the left hand side).
*Unless a company has made excessive and unnecessary use of the dreaded taxonomy extensions.
Five simple steps required for each company you wish to compare.
Step 1 - Load instance document. Arelle allows you to load this directly from the web if you don't feel the need to download and store it locally.
Choose "Open Web..." from the File menu and copy the URL of the instance document into the input box (shown above). There are two ways to find this - the slow way & the quick way. The slow way requires you to click on the "SEC Search" button which takes you to the EDGAR search page, find the company you are looking for, search for the filing etc etc etc.......You may find it quicker to use the "single click" search option available from my website (see post "Easy access to SEC XBRL spreadsheets via a web app").
From my website, enter the company identifier or name, make your single click to search, then right click on the "X" (shown above) for the filing you require and choose to copy the link. Return to Arelle & paste into the input box. Crikey all this just to open an instance document! and that was the easy bit!
Step 2 - Copy the "Fact Table" to Excel. First remove all (well some) of the unwanted (empty) columns. Choose the remove random empty columns option otherwise known as right clicking on the table and choosing "options > ignore dimensions". For more on this, see previous post "Xbrl Tags into Excel using Arelle".
Step 3 - This step isn't entirely necessary but it kinda feels right (and should speed up lookups - see below). Delete all the note sections containing html formatted and therefore difficult to read text by deleting the rows containing this data.
Step 4 - Delete the unwanted columns that the "random" button failed to delete (i.e. most of them). You may need to expand the width of the columns to see which one is which. Don't use the "autofit column width" option to do this quickly as you will end up with some flipping big columns which are then difficult to re-size back to something sensible! Highlight all the columns and set the width manually to something manageable instead. I deleted 19 columns for the Microsoft 10K in the example spreadsheet (see below) to leave me with the 3 key years of data.
Now you in effect have a lookup table with 2 years of balance sheet (or "instance" data in XBRL parlance) and 3 years of "duration" data such as the income statement.
Step 5 - Except lookups won't work because an exact match is needed for unsorted data (would need to be in alpha-numeric order for it to be sorted) and the tags pasted from Arelle have leading spaces consistent with the presentation hierarchy, so another step is needed. Insert a new column in front of the tags and fill it with the following formula "=trim(B1)" using a relative cell reference to replicate the "tags" column but with the leading spaces removed (as shown above).
Now do it all over again for the next company you wish to compare! putting it in a new sheet.
Because the tags are the same* regardless of which company you are looking at, you can now use Excel's lookup functions to create standard reports for comparative analysis. Order is unimportant for exact lookup functions, which is what enables us to do this regardless of how the company has chosen to present the data.
The beauty of this is that you can load the data "as presented" whilst viewing the data in a standardised format customised to your choice. Standardised and as presented data connected and all in the same file. Now that is powerful and only possible because of XBRL. More on the mechanics of how to create a standard report for multiple companies in my next post. For now have a look at the example spreadsheet (snippets above) which you can download from my website - www.xbrlxl.com (follow the "Spreadsheet Examples" link on the left hand side).
*Unless a company has made excessive and unnecessary use of the dreaded taxonomy extensions.
Labels:
arelle,
as presented,
comparative analysis,
edgar,
excel,
fact table,
instance document,
sec,
single click,
spreadsheet,
xbrl,
xbrl tags
Thursday, 24 November 2011
Easy access to SEC XBRL spreadsheets via a web app
Thought I ought to act on my last blog post and make things even easier. So I've created a simple web app to speed up downloading XBRL spreadsheets into Excel. Nothing special - just saves you a few clicks and some messing around when all you want to do is analyse a company in Excel. It can be found at www.xbrlxl.com. All that's required is a simple login, a couple of clicks and away you go.
(Update)
This has been updated so you can now download and compare multiple companies using their XBRL tags. See my later post Instant comparisons of XBRL data in Excel. It's still possible to access the SEC financial report spreadsheet by clicking on the filing type (e.g 10-K) in a list of filings produced by a search.
(Update)
This has been updated so you can now download and compare multiple companies using their XBRL tags. See my later post Instant comparisons of XBRL data in Excel. It's still possible to access the SEC financial report spreadsheet by clicking on the filing type (e.g 10-K) in a list of filings produced by a search.
Labels:
2 clicks,
analyze,
app,
application,
direct,
easy,
excel,
spreadsheet,
xbrl
Friday, 18 November 2011
Accessing SEC XBRL spreadsheets directly
As I mentioned in a previous post - Seeing XBRL for free, you can circumnavigate the SEC viewer and go directly to a pre-canned spreadsheet of the entire filing!
Here's the specifics of how to do it:
Use a URL with the following format:
http://www.sec.gov/Archives/edgar/data/[CIK]/[Accession No]/Financial_Report.xls
where [CIK] and [Accession No] are the unique filer and filing identifiers you need to insert which can be found by doing an Edgar search or in an RSS feed of Edgar filings. The Accession Number must be a fixed length of 18 digits so must include any leading zero's. The opposite is true for the CIK - variable length and no leading zero's.
So if you wanted the 2011 Apple 10-K in Excel you would create the following link. Click on it and it will download.
http://www.sec.gov/Archives/edgar/data/320193/000119312511282113/Financial_Report.xls
Here's the specifics of how to do it:
Use a URL with the following format:
http://www.sec.gov/Archives/edgar/data/[CIK]/[Accession No]/Financial_Report.xls
where [CIK] and [Accession No] are the unique filer and filing identifiers you need to insert which can be found by doing an Edgar search or in an RSS feed of Edgar filings. The Accession Number must be a fixed length of 18 digits so must include any leading zero's. The opposite is true for the CIK - variable length and no leading zero's.
So if you wanted the 2011 Apple 10-K in Excel you would create the following link. Click on it and it will download.
http://www.sec.gov/Archives/edgar/data/320193/000119312511282113/Financial_Report.xls
Labels:
edgar,
excel,
sec,
spreadsheet,
xbrl
Wednesday, 16 November 2011
Firefox XBRL Add-on
Continuing my trawl through the free viewers.....
As I mentioned in my previous post, the Firefox XBRL Add-on, although apparently not supported, has a couple of tricks up it's sleeve.
With the Firefox XBRL Add-on you can view any of the taxonomies used in the creation of the XBRL and you can drill down into the notes for a financial statement item by clicking on it to reveal a pop up box that will show any links, providing these have been enforced in the original document. Charles Hoffman calls this "metadata leveraging".
He also discovered that you can do some crazy stuff by dragging & dropping the headings around like you can in an Excel pivot table to totally customise the view. You can do this with any heading with a triangle in the top left hand corner. You can swap them round or drop them onto "[DRAG PAGING COLUMNS HERE]". Not sure how useful it is at this level but it's mildly entertaining. Perhaps more usefully, you can choose to view only specific data items or periods by clicking on the "Item" and "Date" headings (with the triangles in the corner) to reveal lists with check boxes. You can't however save these settings to use with other documents.
And It will turn XBRL into iXBRL and vice versa, although the iXBRL doesn’t always render perfectly but if you wanna turn XBRL into a single document to read offline, it’s fairly adequate.
The Add-on is not based on the Rivet open source code. Don't be put off by the fact that Firefox says it's not compatible with version 5. It will install and work once you relax Mozilla's strict compatibility enforcement in the options. Click on a copy of the instance document on an Edgar filing page and (after a short interlude) the add on will kick in to enable you to see the document. You can also view documents on your hard drive, although it will need a connection to download the taxonomies before it will load.
Of course the fact it is in Firefox maybe a problem. I moved over from Firefox to Chrome last year so it's not where I'd ideally like it.
As I mentioned in my previous post, the Firefox XBRL Add-on, although apparently not supported, has a couple of tricks up it's sleeve.
With the Firefox XBRL Add-on you can view any of the taxonomies used in the creation of the XBRL and you can drill down into the notes for a financial statement item by clicking on it to reveal a pop up box that will show any links, providing these have been enforced in the original document. Charles Hoffman calls this "metadata leveraging".
He also discovered that you can do some crazy stuff by dragging & dropping the headings around like you can in an Excel pivot table to totally customise the view. You can do this with any heading with a triangle in the top left hand corner. You can swap them round or drop them onto "[DRAG PAGING COLUMNS HERE]". Not sure how useful it is at this level but it's mildly entertaining. Perhaps more usefully, you can choose to view only specific data items or periods by clicking on the "Item" and "Date" headings (with the triangles in the corner) to reveal lists with check boxes. You can't however save these settings to use with other documents.
And It will turn XBRL into iXBRL and vice versa, although the iXBRL doesn’t always render perfectly but if you wanna turn XBRL into a single document to read offline, it’s fairly adequate.
The Add-on is not based on the Rivet open source code. Don't be put off by the fact that Firefox says it's not compatible with version 5. It will install and work once you relax Mozilla's strict compatibility enforcement in the options. Click on a copy of the instance document on an Edgar filing page and (after a short interlude) the add on will kick in to enable you to see the document. You can also view documents on your hard drive, although it will need a connection to download the taxonomies before it will load.
Of course the fact it is in Firefox maybe a problem. I moved over from Firefox to Chrome last year so it's not where I'd ideally like it.
Labels:
custom view,
drill down,
firefox add-on,
free,
ixbrl,
taxonomy,
xbrl
Monday, 31 October 2011
Where do I want to see XBRL?
To be frank, if I was an analyst, I would have no interest in viewing XBRL or more specifically the data in which it has been entwined. I don't want to view it, I want to use it, I want to add value to it. I want it in Excel. I still believe that's the best place for it, even if it comes via an intermediary database first. Analysts spent years persuading resistant data vendors to dig the data out of their databases and let it flow into spreadsheets unencumbered by restrictive proprietary software. I don't believe this paradigm is going to change any time soon. Of course there are others who take a different view.
So I'm not going to spend much time talking about the merits of one viewer over another but rather whether they can assist me in getting the data to where I want it. I will note that the only free viewers that are supported (i.e. where there are signs of ongoing development) are all web based and all use the open source code originally made available by Rivet Software at the behest of the SEC.
So don't bother with Rivet Software's Dragon View or XBRL View, both of which are desktop based but are unsupported.
I'm gonna stop here because I prefer to keep my posts short and punchy. There will be a stream of posts coming out over the next few days (well maybe not a stream - more like 2) looking at the viewers.
So I'm not going to spend much time talking about the merits of one viewer over another but rather whether they can assist me in getting the data to where I want it. I will note that the only free viewers that are supported (i.e. where there are signs of ongoing development) are all web based and all use the open source code originally made available by Rivet Software at the behest of the SEC.
So don't bother with Rivet Software's Dragon View or XBRL View, both of which are desktop based but are unsupported.
I'm gonna stop here because I prefer to keep my posts short and punchy. There will be a stream of posts coming out over the next few days (well maybe not a stream - more like 2) looking at the viewers.
Labels:
dragon view,
excel,
free,
rivet,
spreadsheet,
spreadsheet death,
xbrl,
xbrl view,
xbrl viewer
Friday, 30 September 2011
..... so how can you access SEC XBRL data?
Well you can't! without a parser. You can view it, as those nice people at the SEC, seeing there might be an issue here, now use a parser themselves to chuck it into a html page and a spreadsheet for you to download. But haven't you always been able to access it like this? - these files contain no tags so aren't they just the same as the html documents companies have been filing for over a decade? They are certainly no more useful for comparative analysis. Isn’t it all about the tags? This is like giving someone a Ferrari but neglecting to leave them the keys.
It should be stated at this point that if you can handle a parser - were talking about a slice of programming here, you can suck out all the goodness and re-purpose the data to fit your requirements, which is obviously what the big boys are doing.
The SEC were not the only ones to see a problem developing. Even the “Father” of XBRL began to wince at the complexity of it all and opined for something simpler, so he invented XBRLS – the “S” standing for simple! Although, as far as I am aware, this hasn’t got any further than a Wikipedia entry.
Not all regulators have taken the “full on” XBRL path. In the UK, the Inland Revenue & Companies House, the UK depository for legally required admissions, have chosen to use iXBRL as the medium of disclosure. iXBRL makes sense. It is just one document which can be read instantly by a browser but has the tags buried in it. It's almost as if Steve Jobs has gotten hold of XBRL and given it the Apple treatment. I will be looking at iXBRL in more detail in a future entry.
It should be stated at this point that if you can handle a parser - were talking about a slice of programming here, you can suck out all the goodness and re-purpose the data to fit your requirements, which is obviously what the big boys are doing.
The SEC were not the only ones to see a problem developing. Even the “Father” of XBRL began to wince at the complexity of it all and opined for something simpler, so he invented XBRLS – the “S” standing for simple! Although, as far as I am aware, this hasn’t got any further than a Wikipedia entry.
Not all regulators have taken the “full on” XBRL path. In the UK, the Inland Revenue & Companies House, the UK depository for legally required admissions, have chosen to use iXBRL as the medium of disclosure. iXBRL makes sense. It is just one document which can be read instantly by a browser but has the tags buried in it. It's almost as if Steve Jobs has gotten hold of XBRL and given it the Apple treatment. I will be looking at iXBRL in more detail in a future entry.
Friday, 9 September 2011
Inaccessible XBRL
"An intelligent fool can make things bigger and more complex. It takes a touch of genius and a lot of courage to move in the opposite direction" - Einstein
When I first heard about XBRL and it's amazing capabilities from the commentators at the time, I imagined a world of disclosures in which a single document would deliver the graphic brilliance of a pdf annual report combined with the analytical precision of a spreadsheet. I anticipated that the same document could be opened effortlessly in different applications depending on how you wished to view the data.
Fast forward to today....
XBRL reporting, as implemented by the SEC at the behest of XBRL International, requires you to take delivery of no less than seven separate files.
None of these files can be read by any of the tools you find on an average desktop. Not by Excel, by Word, by Explorer or any other web browser or Abobe Reader. Not by using the latest versions. Not even by jigging them around a bit. This may surprise you, seeing Microsoft were part of the original consortium. I can only assume their involvement was nominal. Perhaps it's never advisable to send a junior to a standards committee meeting, even if they plan to spend the entire afternoon discussing data labels.
When I first heard about XBRL and it's amazing capabilities from the commentators at the time, I imagined a world of disclosures in which a single document would deliver the graphic brilliance of a pdf annual report combined with the analytical precision of a spreadsheet. I anticipated that the same document could be opened effortlessly in different applications depending on how you wished to view the data.
Fast forward to today....
XBRL reporting, as implemented by the SEC at the behest of XBRL International, requires you to take delivery of no less than seven separate files.
None of these files can be read by any of the tools you find on an average desktop. Not by Excel, by Word, by Explorer or any other web browser or Abobe Reader. Not by using the latest versions. Not even by jigging them around a bit. This may surprise you, seeing Microsoft were part of the original consortium. I can only assume their involvement was nominal. Perhaps it's never advisable to send a junior to a standards committee meeting, even if they plan to spend the entire afternoon discussing data labels.
Labels:
analysis,
complex,
disclosures,
excel,
inaccessible,
microsoft,
reporting,
sec,
xbrl,
xbrl international
Thursday, 4 August 2011
Why was XBRL invented?
"Progress isn't made by early risers. It's made by lazy men trying to find easier ways of doing something" - The science fiction writer, Robert Heinlein
Before the advent of XBRL, comparative analysis would require the mass re-keying of data. As a man who once did this for a living, it's a enough to make you want to roll over and go back to sleep! Not only is it laborious, it's error prone, expensive (we did like to get paid!) and time-consuming (leading to long lags between publication of company financial data and it appearing on a screen near you). The Architects of XBRL were trying to solve these problems and also eliminate one further stage, invisible to user, in the production of accounting data - the transfer of the data from the accounting system to the prettified published accounts. Indeed in the science fiction world of XBRL, the numbers in the back office accounting system may not have been keyed in at all but arrive in the form of an XBRL enabled invoice.
So as ever, it's about saving time and money with the added advantage of being able to have greater confidence in data which has been untouched by error prone human hands.
Before the advent of XBRL, comparative analysis would require the mass re-keying of data. As a man who once did this for a living, it's a enough to make you want to roll over and go back to sleep! Not only is it laborious, it's error prone, expensive (we did like to get paid!) and time-consuming (leading to long lags between publication of company financial data and it appearing on a screen near you). The Architects of XBRL were trying to solve these problems and also eliminate one further stage, invisible to user, in the production of accounting data - the transfer of the data from the accounting system to the prettified published accounts. Indeed in the science fiction world of XBRL, the numbers in the back office accounting system may not have been keyed in at all but arrive in the form of an XBRL enabled invoice.
So as ever, it's about saving time and money with the added advantage of being able to have greater confidence in data which has been untouched by error prone human hands.
Labels:
error-free data,
re-keyed data,
science fiction,
time and money,
xbrl
Tuesday, 2 August 2011
Why XBRL for Analysis?
The purpose of this blog is to record my thoughts and observations about the usefulness of xbrl published data in the process of preparing company data for investment or credit analysis and in so doing aid those considering the use of xbrl data in their analytical models. Is it the panacea that it's proponents claim or does it fall short? I've started this blog now because as of today 2,106 US companies have filed xbrl data so we are quickly reaching a point where comparative analysis of xbrl data becomes a valid option.
Labels:
analysis,
comparative analysis,
credit analysis,
investment analysis,
panacea,
useful,
valid,
xbrl
Subscribe to:
Posts (Atom)
